
短期 vs 长期:一句话区分
| 短期记忆 | 长期记忆 | |
|---|---|---|
| 记录范围 | 会话级(线程 Thread)的数据 | 用户特定或应用级的数据 |
| 会话间 | 不共享 | 任何会话都可以随时访问 |
| 例子 | 刚才聊了什么 | "你喜欢简短回答"、"你偏好 Python"、"某个用户是 VIP"、"某个流程过去怎么做效果更好" |
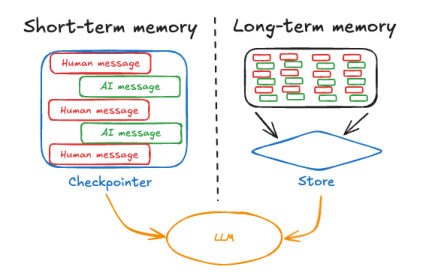 图:短期记忆走 Checkpointer、长期记忆走 Store,最后一起喂给模型
这类信息不属于某一条聊天,而属于"用户/组织/应用本身"——所以不能塞在某个 thread 的 messages 里。
长期记忆分三类
LangChain 参考 CoALA 论文把长期记忆划分为三类:
| 类型 | 存什么 | 例子 |
|---|---|---|
| Semantic(语义记忆) | 事实 | 用户喜欢简洁回答、常用中文、某公司属于哪个行业 |
| Episodic(情景记忆) | 经验 | 过去某个任务是怎么成功的、某种输入下怎么回答效果最好(在 Agent 里常表现为 few-shot 示例) |
| Procedural(程序性记忆) | 规则/做事方法 | 系统提示词、工作流程、工具调用规则 |
情景记忆的思路值得记住:不直接告诉模型规则,而是给它看几个"输入 → 输出"的例子,让它照着学。
存储架构:四层结构
长期记忆的存储是 store → namespace → key → value 的四层架构:
| 层 | 说明 | 数据类型 |
|---|---|---|
| Store(记忆仓库) | langgraph.store.base.BaseStore 的子类实例。常用实现:InMemoryStore(测试)、PostgresStore(生产) | 对象 |
| Namespace(命名空间) | 层级路径,作用很像"文件路径/文件夹",用于分组和隔离记忆 | 字符串元组 tuple[str, ...] |
| Key(键) | 该 namespace 下的唯一标识 | str |
| Value(值) | 存储的内容 | dict[str, Any] |
namespace = ("users", "user_123", "preferences")   # 元组类型
key = "profile"                                     # 字符串类型
value = {                                           # 字典类型
    "language": "zh-CN",
    "style": "short_direct",
    "likes": ["python", "rag"],
}
store.put(namespace, key, value)
同一个 AI 应用通常这样组织:每个会话有自己的短期状态 State(按 thread_id 区分),而长期记忆共享同一个 Store 实例,再通过 namespace 区分不同用户、组织、业务域:
AI 应用
├─ thread_id = t1 → state_1
│   ├─ messages = [{"role": "user", "content": "我想去北京旅游"}, ...]
│   ├─ current_intent = "travel_planning"
│   └─ collected_slots = {"destination": "北京"}
├─ thread_id = t2 → state_2
│   ├─ messages = [{"role": "user", "content": "帮我写周报"}]
│   └─ ...
└─ store(跨会话共享)
    └─ namespace ("users", "alice", "memories")
        ├─ key "pref_food" → {...}
        └─ key "pref_lang" → {...}
三个基础 API
LangChain 1.2.x 的长期记忆基于 store 持久化数据,API 有三个:put() 写入、get() 读取、search() 检索。它们可以在 Agent 执行流程之外直接调用。
put() / get()
store.put(
    ("users", "Alice", "memories"),      # namespace
    "pref_food",                          # key
    {"category": "food", "text": "Alice likes sushi"},   # value
)

item = store.get(("users", "Alice", "memories"), "pref_food")
print(item.value)      # {'category': 'food', 'text': 'Alice likes sushi'}
put() 的签名(本机核对过源码):
def put(
    self,
    namespace: tuple[str, ...],
    key: str,
    value: dict[str, Any],
    index: Literal[False] | list[str] | None = None,
    *,
    ttl: float | None | NotProvided = NOT_PROVIDED,
) -> None:| 参数 | 说明 |
|---|---|
namespace / key / value | 层级路径 / 唯一键 / 要保存的 JSON-like 字典 |
index | 控制语义检索索引,三档语义见下表 |
ttl | 可选过期时间(是否支持取决于具体 store 实现) |
index 的三种取值要分清:
| 取值 | 语义 |
|---|---|
None(默认) | 用 store 初始化时配置的索引配置;如果初始化时没有指定索引策略,这个参数会被直接忽略 |
False | 不为该 item 建语义索引(数据照样存,只是搜不到) |
list[str] | 只对指定字段路径建索引 |
get() 的签名:
def get(
    self,
    namespace: tuple[str, ...],
    key: str,
    *,
    refresh_ttl: bool | None = None,
) -> Item | None:| 参数 | 说明 |
|---|---|
namespace / key | 层级路径 / 该路径下的唯一键 |
refresh_ttl | 是否刷新当前 item 的 TTL(time-to-live,存活时间)。默认 None 表示沿用创建 store 时指定的同名配置;没配置 TTL 时该参数被忽略 |
TIP
实测 get() 返回的不是裸 value,而是一个 Item 对象(字段有 key、namespace、value、created_at、updated_at、dict)。所以取值要写 item.value——别忘了 .value。
created_at / updated_at:InMemoryStore 与 PostgresStore 不一样
Item 上新增了 created_at(创建时间)和 updated_at(更改时间),但两种 store 的语义完全不同:
| InMemoryStore | PostgresStore | |
|---|---|---|
| 更新逻辑 | 每次 put 都新建一个 Item 对象(无论 namespace/key 是否相同) | 真正的 update,不是覆盖 |
created_at | 每次 put 都被重置 | 固定为 Item 首次创建的时间 |
updated_at | 跟着一起重置 | 每次更新时改变 |
| 两者关系 | 永远相等(同一次 datetime.now()) | 可能不同,符合直觉 |
看源码就明白了——InMemoryStore 的 _apply_put_ops 里,不管这条 key 之前存不存在,都直接盖一个新 Item 上去:
def _apply_put_ops(self, put_ops):
    for (namespace, key), op in put_ops.items():
        if op.value is None:
            self._data[namespace].pop(key, None)
            self._vectors[namespace].pop(key, None)
        else:
            self._data[namespace][key] = Item(
                value=op.value,
                key=key,
                namespace=namespace,
                created_at=datetime.now(timezone.utc),   # ← 每次都重新取
                updated_at=datetime.now(timezone.utc),   # ← 每次都重新取
            )
PostgresStore 的用法和 PostgresSaver 如出一辙——from_conn_string + setup():
from langgraph.store.postgres import PostgresStore

DB_URL = "postgresql://langchain_user:abcd1234@<你的IP>:5432/langchain_db?sslmode=disable"

with PostgresStore.from_conn_string(DB_URL) as store:
    store.setup()                                    # ← 第一次跑,建 store 相关表
    store.put(("users",), "user-11", {"name": "小蓝"})
    print(store.get(("users",), "user-11"))
    # Item(..., created_at='2026-06-11T23:24:31.132342+08:00', updated_at='2026-06-11T23:24:31.132342+08:00')

    store.put(("users",), "user-11", {"name": "小红"})   # 更新同一条
    print(store.get(("users",), "user-11"))
    # Item(..., created_at='2026-06-11T23:24:31.132342+08:00',   ← 没变
    #            updated_at='2026-06-11T23:26:11.956257+08:00')   ← 变了
TIP
本机实测(InMemoryStore,同一 namespace/key 先写"小蓝"、隔 1.2 秒再写"小红"):
首次 put: Item(..., created_at='...12:09:27.014794+00:00', updated_at='...12:09:27.014800+00:00')
再次 put: Item(..., created_at='...12:09:28.215231+00:00', updated_at='...12:09:28.215235+00:00')
两次的 created_at 都跟着 put 一起往后跳了——证明"更新"在 InMemoryStore 里其实是新建。注意:两次时间戳相差仅 6 微秒(014794 vs 014800),是同一行里两次 datetime.now() 的差值,不是"相等"——课程正文写的是"created_at 和 updated_at 始终一致",本机看是"始终相差几微秒",但结论一样:它们总是同一次 put 的产物,不能用来区分创建和修改。要区分创建/修改时间,得换 PostgresStore。
search()
store.search(
    ("users",),                       # namespace_prefix:在该前缀下搜索
    query="用户喜欢什么食物",           # 语义检索的自然语言(需要向量支持)
    filter={"category": "food"},       # 结构化过滤:按 value 里的键值对筛
    limit=10,
    offset=0,
)| 参数 | 说明 |
|---|---|
namespace_prefix | 命名空间前缀,在该前缀下搜索(位置参数) |
query | 语义检索用的自然语言,需要把输入转成向量 |
filter | 结构化过滤:用 value 里的键值对筛选 |
limit / offset | 最多返回几条 / 跳过前几条(相当于 SQL 的 limit / offset) |
refresh_ttl | 是否刷新过期时间 |
它支持两种检索方式:
- 按
filter做结构化过滤(精确匹配,不需要向量) - 按
query做语义相似度检索(需要向量支持)
返回值是 SearchItem 列表,额外携带匹配分数等检索元信息。
TIP
实测(InMemoryStore):search(("users",)) 能按前缀拿到全部 2 条;search(ns, filter={"category": "code"}) 精确筛出 pref_lang;limit=1 只返回第一条。结构化过滤不需要任何模型/向量,开箱即用。
让 search() 支持语义检索:index 配置
上面说的"按 query 语义检索"不是自动就有的——得在创建 store 时通过 index 参数配置,否则 query 无从算起。
from langgraph.store.memory import InMemoryStore

index_config = {
    "embed": embed,        # 把文本转成向量的"嵌入函数"
    "dims": 6,             # 输出向量维度
    "fields": ["$", "course"],   # 给 value 里哪些字段建索引
}
store = InMemoryStore(index=index_config)
IndexConfig 的三个字段(源码):
class IndexConfig(TypedDict, total=False):
    dims: int
    embed: Embeddings | EmbeddingsFunc | AEmbeddingsFunc | str
fields: list[str] | None| 字段 | 说明 |
|---|---|
embed | 把输入文本转成向量的嵌入函数。可以是自定义函数、嵌入模型对象,也可以直接写字符串(模型名,如 "openai:text-embedding-3-large") |
dims | 输出向量维度,必须和 embed 实际产出的维度一致 |
fields | 用于计算向量的属性列表(都是 value 里的 key)。四种写法可以同时出现 |
fields 的四种路径写法(这里讲得比"入门"细,值得单独记):
| 写法 | 含义 |
|---|---|
["$"] | 把整个 value 当作一个整体嵌入 |
["field1", "field2"] | 单独指定某个一级字段 |
["parent.child"] | 从嵌套 JSON 对象里取子字段的值 |
["array[*].field"] | 从 JSON 数组的每个对象里取子字段的值 |
NOTE
fields 列表的每个元素都会生成一个嵌入向量——所以 ["$", "course"] 会为一条 item 生成 2 个向量(一条按整体、一条按 course)。检索时底层做的是 max pooling(同一个 item 的多个向量取最高分),所以你不用操心"命中哪个字段"。
实测:索引到底建了什么
用自定义嵌入函数(返回全 1 向量)能直接把向量结构打出来:
from pprint import pprint

def embed(texts: list[str]) -> list[list[float]]:
    return [[1.0] * 6 for _ in texts]

index_config = {"embed": embed, "dims": 6, "fields": ["$", "course"]}
store = InMemoryStore(index=index_config)
store.put(("users", "Alice", "memories"), "preferences",
          {"course": "计算机组成原理", "sports": "跑步", "food": "紫光园奶皮子酸奶"})

pprint(store._vectors)      # ← 私有属性,仅用于观察
store._vectors 是个 defaultdict,三层结构 namespace → key → 字段名 → 向量:
{('users', 'Alice', 'memories'): {'preferences': {'$': [1.0, 1.0, 1.0, 1.0, 1.0, 1.0],
                                                  'course': [1.0, 1.0, 1.0, 1.0, 1.0, 1.0]}}}
也能按 namespace + key + 字段名只取一个向量:
pprint(store._vectors[('users', 'Alice', 'memories')]['preferences']['$'])
# [1.0, 1.0, 1.0, 1.0, 1.0, 1.0]
TIP
本机实测(自定义嵌入函数记录每次被喂进去的文本,fields=["$", "course", "info.city", "tags[*].name"]):
传给 embed 的文本:
    ['{"course": "数字电路", "info": {"city": "北京", "zip": "100000"}, "tags": [{"name": "ai"}, {"name": "rag"}]}',   ← $
     '数字电路',        ← course(一级字段)
     '北京',            ← info.city(嵌套字段)
     'ai', 'rag']       ← tags[*].name(数组,每个元素一条)
三点结论:
$传进去的是整个 value 的 JSON 字符串(json.dumps后的结果)- 嵌套和数组路径真的被解析了——
info.city拿到'北京',tags[*].name展开成两条文本 - 数组元素会各生成一个向量——
_vectors里存成了tags[*].name.0、tags[*].name.1两个键
真实语义检索:用嵌入模型
把 embed 换成真实的嵌入模型就行。课程用的是 CloseAI 平台的 openai:text-embedding-3-large,它的嵌入维度是 3072,所以 dims 必须写 3072:
from langchain.embeddings import init_embeddings

embedding_model = init_embeddings(
    model="openai:text-embedding-3-large",
    api_key=os.getenv("CLOSEAI_API_KEY"),
    base_url=os.getenv("CLOSEAI_BASE_URL"),
)

index_config = {"embed": embedding_model, "dims": 3072, "fields": ["$"]}
store = InMemoryStore(index=index_config)
配上之后就能按自然语言搜了:
for item in store.search(("users",), query="数电模电"):
    print(item)
# Item(..., value={'course': '数字电路与模拟电路', ...}, score=0.22494289397943232)
# Item(..., value={'course': '数字电路与模拟电路', ...}, score=0.21367212817763243)
# Item(..., value={'course': '计算机组成原理', ...},     score=0.1253981117634029)
WARNING
只给 query 时,返回的是"前缀下全部 item",不是"最相关的几条"——底层对每个候选算 score,然后按 score 降序排列,默认 limit=10 只是把结果截到 10 条。所以语义检索一定要配合 limit(或 filter)用,否则等于"全表返回、只是排了个序"。
本机用假嵌入函数实测(limit 默认 10、库里只有 3 条):3 条全被返回,只是顺序按 score 从高到低;改成 limit=2 才只剩前 2 条。
TIP
本机实测索引开关(同一份数据,只改 put 的 index 参数):
| 场景 | _vectors 里有什么 |
|---|---|
InMemoryStore()(没有 index 配置)+ put(index=["$"]) | 空——没有配置时 index 参数被忽略 |
InMemoryStore(index=cfg) + put()(默认 None) | {'$': [...], 'course': [...]}——按初始化配置建索引 |
InMemoryStore(index=cfg) + put(index=False) | 空,但 store.get() 照样取得到数据(只是搜不到) |
InMemoryStore(index=cfg) + put(index=["course"]) | 只有 {'course': [...]}——只给指定字段建索引 |
在 Agent 里访问长期记忆
我们可以在工具或中间件中访问长期记忆。
在工具中访问
工具函数多接收一个 runtime: ToolRuntime 参数(框架自动注入),通过它拿到 store 和 state:
from typing import NotRequired

from langchain.agents import AgentState, create_agent
from langchain.tools import tool, ToolRuntime
from langgraph.store.memory import InMemoryStore

store = InMemoryStore()

class CustomState(AgentState):
    user_id: NotRequired[str]                 # ← 自定义状态字段

@tool(parse_docstring=True)
def save_user_info(name: str, runtime: ToolRuntime) -> str:
    """将用户信息保存在长期记忆中

    Args:
        name: 用户名

    Returns:
        str: 保存状态
    """
    runtime.store.put(("users",), runtime.state["user_id"], {"name": name})
    return "saved"

@tool(parse_docstring=True)
def get_user_info(runtime: ToolRuntime) -> str:
    """从长期记忆中读取用户信息

    Returns:
        str: 用户信息
    """
    item = runtime.store.get(("users",), runtime.state["user_id"])
    return str(item.value) if item else "unknown"

agent = create_agent(
    model=model,
    tools=[save_user_info, get_user_info],
    store=store,                              # ← 把 store 交给 Agent
    state_schema=CustomState,                 # ← 用自定义状态把 user_id 带进来
    system_prompt="用户提及个人信息时及时记录,用户询问个人信息时尝试用工具检索",
)

agent.invoke({"messages": ["我叫韩立"], "user_id": "user_1"})
三个要点:
| 要点 | 说明 |
|---|---|
工具加 runtime: ToolRuntime 参数 | 框架自动注入,不用你传;runtime.store / runtime.state 都在里面 |
创建 Agent 时传 store=store | 不传的话工具里拿不到 store |
用 state_schema 扩展状态 | 自定义 user_id 这类字段,invoke 时一起传进来(这里传的是 {"user_id": "user_1"}) |
TIP
实测:模型调用 save_user_info 后,store.get(("users",), "user_1") 里就有 {'name': '韩立'} 了;换个会话(甚至换一次进程,只要 store 是持久化的)再读,数据依然在——这就是"跨会话记忆"。
换成 PostgresStore:只改两行
把 InMemoryStore() 换成 PostgresStore.from_conn_string(...),工具代码一个字都不用动:
from typing import NotRequired

from langchain.agents import AgentState, create_agent
from langchain.tools import tool, ToolRuntime
from langgraph.store.postgres import PostgresStore

DB_URI = "postgresql://langchain_user:abcd1234@<你的IP>:5432/langchain_db?sslmode=disable"

class CustomState(AgentState):
    user_id: NotRequired[str]

@tool(parse_docstring=True)
def save_user_info(name: str, runtime: ToolRuntime) -> str:
    """将用户信息保存在长期记忆中

    Args:
        name: 用户名

    Returns:
        str: 保存状态
    """
    runtime.store.put(("users",), runtime.state["user_id"], {"name": name})
    return "saved"

@tool(parse_docstring=True)
def get_user_info(runtime: ToolRuntime) -> str:
    """从长期记忆中读取用户信息

    Returns:
        str: 用户信息
    """
    item = runtime.store.get(("users",), runtime.state["user_id"])
    return str(item.value) if item else "unknown"

with PostgresStore.from_conn_string(DB_URI) as store:      # ← 1. 换 store
    store.setup()                                          # ← 2. 建表(第一次跑)
    agent = create_agent(
        model=model,
        tools=[save_user_info, get_user_info],
        store=store,
        system_prompt="用户提及个人信息时及时记录,用户询问个人信息时尝试用工具检索",
        state_schema=CustomState,
    )

    agent.invoke({"messages": ["你好,很高兴认识你,我是小花"], "user_id": "user-1"})
    agent.invoke({"messages": ["我是谁"], "user_id": "user-1"})     # ← 新会话也能答上来
NOTE
PostgresStore 和 PostgresSaver 的用法完全对称:from_conn_string(DB_URL) 上下文管理器 + setup() 初始化表结构。区别只在于——前者管长期记忆(store 表),后者管短期记忆/检查点(checkpoint_* 表)。
查看 PostgreSQL 里到底建了哪些表
在服务器上连进数据库(psql "postgresql://..."),然后 \dt 看当前 schema 下的所有表:
langgraph_db=> \dt
                     List of relations
 Schema |            Name       | Type  |    Owner
--------+-----------------------+-------+----------------
 public | checkpoint_blobs      | table | langgraph_user
 public | checkpoint_migrations | table | langgraph_user
 public | checkpoint_writes     | table | langgraph_user
 public | checkpoints           | table | langgraph_user
 public | store                 | table | langgraph_user
 public | store_migrations      | table | langgraph_user
(6 rows)六张表,正好对应两个持久化器:
| 表 | 谁建的 | 存什么 |
|---|---|---|
checkpoints | PostgresSaver.setup() | 主表:每个 thread 在某个时刻的 checkpoint 快照 |
checkpoint_blobs | 同上 | 不适合直接内联进 checkpoints.checkpoint 的复杂 channel 值 |
checkpoint_writes | 同上 | 中间写入 / pending writes,不是最终完整 checkpoint |
checkpoint_migrations | 同上 | 迁移版本表(不是业务数据) |
store | PostgresStore.setup() | 长期记忆的 key-value 本体 |
store_migrations | 同上 | 长期记忆的迁移版本表 |
也就是说:只用了
PostgresSaver就只多前 4 张表;再加PostgresStore才多出store和store_migrations两张。课程在"2.2.3 查看持久化数据"里只看到 4 张表,就是因为那一节只用了 checkpointer。
顺带记几个 psql 常用命令(课程演示过):
| 命令 | 作用 |
|---|---|
\l | 列出所有数据库 |
\dn | 列出所有 schema |
select current_schema(); | 查看当前所处的 schema |
\dt | 列出当前 schema 下的所有表 |
PostgreSQL 的存储结构是 Database → Schema → Table(数据库 → 分区 → 表)三层。
在中间件中访问
中间件里通过 runtime.store 读写长期记忆。典型用法是在 before_model 里把用户偏好注入系统提示:
from langchain.agents.middleware import before_model

@before_model
def load_user_preference(state, runtime):
    item = runtime.store.get(("users",), state.get("user_id", ""))
    if item:
        print("已知用户偏好:", item.value)
return None三条访问路径:runtime / request.runtime
不同风格的钩子拿到 runtime 的方式不一样,三条路径要分清:
| 钩子风格 | 具体钩子 | 访问方式 |
|---|---|---|
| Node-style | before_agent / before_model / after_model / after_agent | runtime.store(runtime 是第二个参数) |
| Wrap-style | wrap_model_call | request.runtime.store |
| Wrap-style | wrap_tool_call | request.runtime.store |
Node-style 钩子的签名,runtime 直接作为参数传进来:
def before_model(self, state: StateT, runtime: Runtime[ContextT]) -> dict[str, Any] | None:Runtime 的定义(源码,本机核对字段为 context / store / stream_writer / previous):
@dataclass(**_DC_KWARGS)
class Runtime(Generic[ContextT]):
    context: ContextT = field(default=None)     # type: ignore[assignment]
    """Static context for the graph run, like `user_id`, `db_conn`, etc.

    Can also be thought of as 'run dependencies'."""

    store: BaseStore | None = field(default=None)
    """Store for the graph run, enabling persistence and memory."""

    stream_writer: StreamWriter = field(default=_no_op_stream_writer)
    """Function that writes to the custom stream."""

    previous: Any = field(default=None)
    """The previous return value for the given thread.
    Only available with the functional API when a checkpointer is provided.
    """
...| 字段 | 用途 |
|---|---|
context | 静态运行时上下文(启动时传入、运行中不变),如 user_id、db_conn |
store | 长期记忆(跨会话持久化) |
stream_writer | 写自定义流(第 17 篇的 custom 流式模式) |
previous | 同一 thread 上一次的返回值(只在 functional API + 有 checkpointer 时可用) |
Wrap-style 的 wrap_model_call,runtime 挂在 request 上:
def wrap_model_call(
    self,
    request: ModelRequest[ContextT],
    handler: Callable[[ModelRequest[ContextT]], ModelResponse[ResponseT]],
) -> ModelResponse[ResponseT] | AIMessage | ExtendedModelResponse[ResponseT]:
ModelRequest 的定义:
@dataclass(init=False)
class ModelRequest(Generic[ContextT]):
    """Model request information for the agent."""

    model: BaseChatModel
    messages: list[AnyMessage]                  # excluding system message
    system_message: SystemMessage | None
    tool_choice: Any | None
    tools: list[BaseTool | dict[str, Any]]
    response_format: ResponseFormat[Any] | None
    state: AgentState[Any]
    runtime: Runtime[ContextT]                  # ← store 在这里面
    model_settings: dict[str, Any] = field(default_factory=dict)
    ...
所以 request.runtime.store 就是长期记忆入口。
wrap_tool_call 同理,但 request 换成了 ToolCallRequest:
def wrap_tool_call(
    self,
    request: ToolCallRequest,
    handler: Callable[[ToolCallRequest], ToolMessage | Command[Any]],
) -> ToolMessage | Command[Any]:@dataclass
class ToolCallRequest:
"""Tool execution request passed to tool call interceptors."""
tool_call: ToolCall # 模型产出的 tool call:name / args / id
tool: BaseTool | None # 要调用的工具实例
state: Any # Agent 状态
runtime: ToolRuntime # ← 注意:这里是 ToolRuntime,不是 Runtime
...IMPORTANT
两个 Runtime 不要搞混:中间件的 Node-style 钩子和 wrap_model_call 拿到的是 Runtime(langgraph.runtime);而 wrap_tool_call 的 request.runtime 是 ToolRuntime——它是专门给工具用的、字段更多:
@dataclass
class ToolRuntime(_DirectlyInjectedToolArg, Generic[ContextT, StateT]):
    state: StateT
    context: ContextT
    config: RunnableConfig
    stream_writer: StreamWriter
    tool_call_id: str | None
    store: BaseStore | None
Runtime | ToolRuntime | |
|---|---|---|
| 出现位置 | 中间件的 Node-style 钩子、ModelRequest.runtime | 工具函数参数、ToolCallRequest.runtime |
| 独有字段 | previous(上次返回值) | config、tool_call_id |
| 共有字段 | context、store、stream_writer | 同左 |
TIP
本机实测(ToolCallRequest / ToolRuntime 的字段用 __dataclass_fields__ 打印核对):ToolCallRequest 是 tool_call / tool / state / runtime;ToolRuntime 是 state / context / config / stream_writer / tool_call_id / store;Runtime 是 context / store / stream_writer / previous——和课程源码一致。ToolRuntime 的泛型默认值是 ContextT = TypeVar("ContextT", default=None)、StateT = TypeVar("StateT", default=dict)。
何时写入记忆
官方介绍两种时机:
| 方式 | 做法 | 优点 | 缺点 |
|---|---|---|---|
| 主流程写(hot path) | 用户发消息,AI 一边回答一边决定要不要记 | 立即生效、下一轮就能用、用户可感知(透明) | 增加延迟、逻辑变复杂 |
| 后台写(background) | 先回答用户,记忆整理放到后台异步做 | 主流程更快、记忆逻辑独立、适合批量整理 | 不能立刻生效、要决定整理频率、触发时机不好选 |
工程上通常这么选:
- 用户偏好、账号资料 → 适合热路径写
- 对话摘要、经验沉淀、行为分析 → 更适合后台写
附:静态运行时上下文(课后阅读)
静态运行时上下文(Static runtime Context) 表示不可变的数据,比如用户元数据、工具、数据库连接对象。通常在运行开始时通过 invoke / stream 的 context 参数传递,运行期间不会更改。
用法要点:
| 位置 | 访问方式 |
|---|---|
| Node-style 钩子中 | 通过 runtime.context 访问 |
| 定义方式 | 用户自定义 ContextSchema 用 @dataclass 修饰 |
| 传入 | agent.invoke(..., context=UserContext(user_id="user_1")) |
一个典型场景:创建 Agent 时声明 context_schema=UserContext,然后在钩子里用 runtime.context.user_id 去长期记忆里查用户额度,额度用尽就中断流程。
记住区别就行:
context是"启动时传入、运行中不变"的参数,适合放数据库连接、用户身份这类东西;state是运行中不断变化的状态;store是跨会话的持久记忆。
定义 ContextSchema:@dataclass + context_schema
三步走:@dataclass 定义 → 创建 Agent 时用 context_schema= 声明 → invoke 时用 context= 传入。
from dataclasses import dataclass

from langchain.agents import create_agent

@dataclass
class UserContext:
    username: str

agent = create_agent(
    model=model,
    store=store,
    context_schema=UserContext,     # ← 声明用哪个 schema
)

agent.invoke(
    {"messages": ["你好啊,你知道 Ada Lovelace 的贡献吗?"]},
    context=UserContext(username="Ada Lovelace"),   # ← 每次调用传入具体值
)
WARNING
课程 PDF 正文 P60 把参数名误写成了 state_schema(原文:"用户自定义 ContextSchema 用 @dataclass 修饰,在Agent创建时通过 state_schema 参数传递")。正确写法是 context_schema——PDF 里同一节的示例代码用的就是 context_schema=UserContext,state_schema 是另一回事(它用于扩展 state,比如上一篇的 CustomState(user_id))。两个参数在 create_agent 里同时存在、互不替代:
create_agent(..., state_schema=CustomState, context_schema=UserContext) # 可以一起用4.1.1 Node-style hooks 中访问 context
Node-style 的四个钩子都通过 runtime.context 访问上下文对象。课程的例子是额度校验:从长期记忆里查用户额度,额度用尽就 jump_to="end" 中断流程。
from dataclasses import dataclass
from typing import Any

from langchain.agents import create_agent
from langchain.agents.middleware import AgentMiddleware, AgentState, hook_config
from langchain_core.messages import AIMessage
from langgraph.runtime import Runtime
from langgraph.store.memory import InMemoryStore

store = InMemoryStore()
namespace = ("users", "credits")
store.put(namespace, "Ada Lovelace", {"tokens_credit_left": 5000, "user_level": 5})
store.put(namespace, "Blackwell",    {"tokens_credit_left": 2999, "user_level": 5})
store.put(namespace, "Ampere",       {"tokens_credit_left": 1000, "user_level": 5})

@dataclass
class UserContext:
    username: str

class CheckCredit(AgentMiddleware):
    @hook_config(can_jump_to=["end"])          # ← 类写法要跳转,必须加这个装饰器
    def before_model(self, state: AgentState, runtime: Runtime) -> dict[str, Any] | None:
        store = runtime.store
        context = runtime.context               # ← 静态上下文

        username = context.username
        credit = store.get(namespace, username)

        if not credit:                          # 查无此人
            return {"jump_to": "end", "messages": AIMessage("您尚未注册~")}

        if credit.value["tokens_credit_left"] < 3000:     # 额度不足
            return {"jump_to": "end", "messages": AIMessage(f"{username}额度不足,请充值")}

        return None

    def after_model(self, state: AgentState, runtime: Runtime) -> dict[str, Any] | None:
        store = runtime.store
        context = runtime.context

        username = context.username
        credit = store.get(namespace, username)

        # 用上一条 AIMessage 的 usage_metadata 算本次消耗
        usage_metadata = state["messages"][-1].usage_metadata
        token_usage = usage_metadata["input_tokens"] + usage_metadata["output_tokens"] * 6
        credit.value["tokens_credit_left"] -= token_usage

        # 更新长期记忆
        store.put(namespace, username, credit.value)
        return None

    def after_agent(self, state: AgentState, runtime: Runtime) -> dict[str, Any] | None:
        store = runtime.store
        context = runtime.context

        username = context.username
        item = store.get(namespace, username)
        print(f"{username} 当前剩余额度:{item.value['tokens_credit_left']}")
        return None

agent = create_agent(
    model=model,
    middleware=[CheckCredit()],
    store=store,
    context_schema=UserContext,
)
同一个 Agent,invoke 时换 context 就换身份——额度够的正常回答,不够的直接被拦下(课程输出):
Ada Lovelace 当前剩余额度:2721
Blackwell 当前剩余额度:2999
============================== -> Ada Lovelace messages <-
你好啊,你知道 Ada Lovelace 的贡献吗?      ← 正常回答(很长的介绍)
============================== -> Blackwell messages <-
你好啊,你知道 Blackwell 的贡献吗?
Blackwell额度不足,请充值 ← 模型根本没被调用| 钩子 | 干了什么 |
|---|---|
before_model | 查额度:没注册 / 额度 < 3000 → jump_to="end" + 一条兜底 AIMessage,模型不会被调用 |
after_model | 从 usage_metadata 算出 token 消耗(输入 + 输出 × 6,输出按 6 倍计价),扣减后写回 store |
after_agent | 整个 Agent 跑完后,从 store 读最新额度打印出来 |
TIP
本机假服务端实测(额度 5000 的用户跑一轮,假服务端返回 usage: {prompt_tokens:1, completion_tokens:1}):
[after_agent] Ada Lovelace 当前剩余额度:4993        ← 5000 - (1 + 1×6) = 4993
store 里现在是: {'tokens_credit_left': 4993, 'user_level': 5}
[after_agent] Ampere 当前剩余额度:1000
Ampere -> 最后一条: Ampere额度不足,请充值           ← 被 before_model 拦下,额度一分没扣
三点确认:① 扣费公式真的按 输入 + 输出 × 6 算(1 + 6 = 7,5000 → 4993);② 被拦截的用户额度不变(before_model 直接跳 end,after_model 没机会跑);③ 写回的是整个 credit.value,所以 user_level 等其他字段一起被保留下来。
4.1.2 Wrap-style hooks 中访问 context
Node-style 钩子用 runtime.context,Wrap-style 钩子用 request.runtime.context。
wrap_model_call:按用户身份裁剪工具集
本例通过 context 里的用户身份,动态决定这次调用暴露给模型哪些工具——额度/权限存在长期记忆里,用 request.runtime.store 读出来:
from dataclasses import dataclass
from typing import Callable

from langchain.agents import create_agent
from langchain.agents.middleware import AgentMiddleware, ModelRequest, ModelResponse
from langchain.tools import tool
from langgraph.store.memory import InMemoryStore

store = InMemoryStore()
namespace = ("users", "credits")
store.put(namespace, "Ada Lovelace", {"tokens_left": 3000, "get_weather": "yes", "get_news": "no"})
store.put(namespace, "Blackwell",    {"tokens_left": 2000, "get_weather": "no",  "get_news": "yes"})

@tool
def get_weather(city: str):
    """查询指定城市当日天气

    Args:
        city: 城市名称
    """
    return f"{city} 今天天气不错"

@tool()
def get_news():
    """查询当日新闻"""
    return "美伊尚未达成停战协议"

@dataclass
class UserContext:
    username: str

class CheckCredit(AgentMiddleware):
    def wrap_model_call(
        self,
        request: ModelRequest,
        handler: Callable[[ModelRequest], ModelResponse],
    ) -> ModelResponse:
        context = request.runtime.context            # ← 静态上下文
        store = request.runtime.store                # ← 长期记忆

        value = store.get(namespace, context.username).value
        tools = []
        for tool in request.tools:
            tool_name = tool.name
            if value[tool_name] == "yes":
                tools.append(tool)
            else:
                print(f"{context.username} 无权调用 {tool_name}")

        # 更改调用请求携带的工具集,仅本次生效(transient request update)
        request = request.override(tools=tools)
        return handler(request)

agent = create_agent(
    model=model,
    middleware=[CheckCredit()],
    tools=[get_weather, get_news],
    store=store,
    context_schema=UserContext,
)三个用户拿到的是三套不同的工具集(课程输出):Ada Lovelace 被拒 get_news、Blackwell 被拒 get_weather、Ampere 两个都有——同一份代码,靠 context 区分。
TIP
本机假服务端实测(CheckCredit + 按工具名自动回 tool_call 的假服务端):
===== Ada Lovelace =====
   [wrap_model_call] Ada Lovelace 无权调用 get_news
   [wrap_tool_call] Ada Lovelace 调用 get_weather 花费 10,剩余额度 2990
   store: {'tokens_left': 2990, 'get_weather': 'yes', 'get_news': 'no'}
===== Blackwell =====
   [wrap_model_call] Blackwell 无权调用 get_weather
   最终回答: 我没有可用的工具
坐实两点:① request.override(tools=...) 真的改掉了发往模型的工具列表——假服务端收到的 tools 里只剩被放行的那个;② 改动是"仅本次"的,下一轮 request.tools 又是完整的全量工具,不会累积。
wrap_tool_call:额度校验 + 写回长期记忆
在 wrap_model_call 的基础上再加一道工具级闸门:额度不够就直接拒绝(连 handler 都不调),够就先扣费、写回 store,再放行。
from typing import Any, Callable

from langchain.agents.middleware import AgentMiddleware, ModelRequest, ModelResponse, ToolCallRequest
from langchain_core.messages import ToolMessage
from langgraph.types import Command

# 每个工具的"话费"
CREDIT_MAP = {"get_weather": 10, "get_news": 20}

class ToolGuard(AgentMiddleware):
    def wrap_tool_call(
        self,
        request: ToolCallRequest,
        handler: Callable[[ToolCallRequest], ToolMessage | Command[Any]],
    ) -> ToolMessage | Command[Any]:
        store = request.runtime.store
        context = request.runtime.context

        username = context.username
        value = store.get(namespace, username).value
        tool_name = request.tool.name

        credits_cost = CREDIT_MAP.get(tool_name)     # 本次调用花费
        credits_left = value["tokens_left"]          # 剩余额度

        if credits_left < credits_cost:
            print(f"{username} 额度不足,{tool_name} 调用失败!")
            # 直接返回一条 ToolMessage,不调用 handler —— 工具根本没执行
            return Command(
                update={
                    "messages": [
                        ToolMessage(
                            content="额度不足,无法调用工具,请充值~",
                            tool_call_id=request.runtime.tool_call_id,   # ← 必须回填,配对 tool_call
                        )
                    ]
                }
            )

        # 更新剩余额度并写回长期记忆
        credits_left -= credits_cost
        value["tokens_left"] = credits_left
        store.put(namespace, username, value)

        return handler(request)
两个细节值得记:
| 细节 | 说明 |
|---|---|
拒绝时返回 Command(update={"messages": [ToolMessage(...)]}) | 不调 handler(request) 工具就不会执行;但必须给一条 ToolMessage,否则模型那边"工具调用没有回音",流程会卡住 |
tool_call_id=request.runtime.tool_call_id | 工具结果要和模型发出的 tool_call 配对,这个 id 不能少 |
TIP
本机假服务端实测(CheckCredit + ToolGuard 串联,Ada Lovelace 额度 3000、get_weather 花费 10):
[wrap_model_call] Ada Lovelace 无权调用 get_news
[wrap_tool_call]  Ada Lovelace 调用 get_weather 花费 10,剩余额度 2990
store: {'tokens_left': 2990, 'get_weather': 'yes', 'get_news': 'no'}
额度真的被扣掉并写回了 store(3000 → 2990),而且这是在没有真实模型的情况下跑通的——说明这一整套"鉴权 + 计费"逻辑完全跑在中间件里,和模型无关。
4.1.3 便捷中间件 @dynamic_prompt:动态系统提示词
@dynamic_prompt 的底层实现和通用钩子函数是统一的,只是给"动态提示词"这个高频需求开了个更便捷的入口。
本例:按 context 里的用户名 + store 里的 chat_preferences,动态生成系统提示词。
from dataclasses import dataclass

from langchain.agents import create_agent
from langchain.agents.middleware import dynamic_prompt, ModelRequest
from langgraph.store.memory import InMemoryStore

store = InMemoryStore()
namespace = ("users", "preferences")
store.put(namespace, "Ada Lovelace", {"chat_preferences": ["不喜欢啰嗦", "尽可能用最精简的文字解释清楚"]})
store.put(namespace, "Blackwell",    {"chat_preferences": ["喜欢长篇大论、引经据典"]})

@dataclass
class UserContext:
    username: str

@dynamic_prompt
def personalized_prompt(request: ModelRequest) -> str:
    username = request.runtime.context.username
    preferences = request.runtime.store.get(namespace, username).value["chat_preferences"]
    custom_prompt = "# 用户偏好\n" + "\n".join(preferences)
    print(f"{username} 自定义系统提示词\n{custom_prompt}")
    return custom_prompt            # ← 返回的就是这次的 system prompt

agent = create_agent(
    model=model,
    middleware=[personalized_prompt],
    store=store,
    context_schema=UserContext,
)
效果对比(同一个问题"为什么花儿这样红?"):
| 用户 | 动态生成出的系统提示词 | 模型回答风格 |
|---|---|---|
| Ada Lovelace | # 用户偏好\n不喜欢啰嗦\n尽可能用最精简的文字解释清楚 | 一句话:"花儿红的主要原因是花瓣细胞中的花青素在酸性环境下显红色……" |
| Blackwell | # 用户偏好\n喜欢长篇大论、引经据典 | 长篇大论:分"科学视角 / 文学艺术 / 文化差异 / 现代发现"四大段 |
IMPORTANT
@dynamic_prompt 只改"本次调用前的系统提示词",不写进消息列表。所以模型输出能看出提示词生效了,但翻 response["messages"] 是看不到这条提示词的。
本机假服务端实测(抓发往模型的原始请求 + 返回的 state):
=== 发给模型的 system 消息 ===
  role=system: # 用户偏好
不喜欢啰嗦
尽可能用最精简的文字解释清楚
  role=user: 为什么花儿这样红?

=== 返回 state 里的消息 ===
  HumanMessage: 为什么花儿这样红?
AIMessage: 好的。请求里有 system 消息,state["messages"] 里没有——这正是它和"往消息列表里插 SystemMessage"的本质区别。顺带一提,这也解释了为什么它能每次调用重新算:如果写进消息列表,第二次调用就会把上次的提示词一起带上,越滚越多。
4.2 工具中访问 context
工具里拿静态上下文靠 runtime.context。上面用的是 runtime.state["user_id"](把用户 id 放 state 里),这里换成放 context 里——顺便演示工具参数用 pydantic 模型的写法。
先说一个前提:参数类型注解是 pydantic 模型时,LangChain 会自动把它解析进工具的 schema。用 convert_to_openai_tool 一看便知:
from typing import List

from pydantic import BaseModel, Field
from langchain.tools import tool
from langgraph.prebuilt.tool_node import ToolRuntime
from langchain_core.utils.function_calling import convert_to_openai_tool

class UserInfo(BaseModel):
    username: str = Field(description="用户名")
    age: int = Field(description="年龄")
    hobbies: List[str] = Field(description="兴趣爱好")

@tool(parse_docstring=True)
def save_user_info(user_info: UserInfo, runtime: ToolRuntime) -> str:
    """保存用户信息

    Args:
        user_info: 用户信息对象
    """
    return "ok"

print(convert_to_openai_tool(save_user_info))
输出的 JSON Schema 里,user_info 被完整展开成了对象(properties 里是 username / age / hobbies,required 三项全要),而 runtime: ToolRuntime 压根没出现:
{
  "type": "function",
  "function": {
    "name": "save_user_info",
    "description": "保存用户信息",
    "parameters": {
      "properties": {
        "user_info": {
          "properties": {
            "username": { "description": "用户名", "type": "string" },
            "age":      { "description": "年龄",   "type": "integer" },
            "hobbies":  { "description": "兴趣爱好", "items": {"type": "string"}, "type": "array" }
          },
          "required": ["username", "age", "hobbies"],
          "type": "object",
          "description": "用户信息对象"
        }
      },
      "required": ["user_info"],
      "type": "object"
    }
  }
}
TIP
本机实测:convert_to_openai_tool(save_user_info) 的输出与课程逐字一致(user_info 被展开、runtime 被隐藏)。
完整案例:读写长期记忆里的用户信息,用户 id 从 context 拿,工具参数用 pydantic 模型:
from dataclasses import dataclass
from typing import Any, List

from pydantic import BaseModel, Field

from langchain.agents import create_agent
from langchain.tools import tool
from langchain_core.messages import HumanMessage, SystemMessage
from langgraph.checkpoint.memory import InMemorySaver
from langgraph.prebuilt.tool_node import ToolRuntime
from langgraph.store.memory import InMemoryStore

@dataclass
class UserContext:
    user_id: str

store = InMemoryStore()
namespace = ("users", "user_info")

class UserInfo(BaseModel):
    username: str = Field(description="用户名", default="unknown")
    age: int = Field(description="年龄", default=0)
    # 这里相当于告诉模型,每次创建新实例时,调用 list() 创建一个新的 list 传进去
    hobbies: List[str] = Field(description="兴趣爱好", default_factory=list)
    # 这种写法是用可变对象做默认值,会有多个对象共享一个列表对象的风险
    # hobbies: List[str] = Field(description="兴趣爱好", default=[])

@tool(parse_docstring=True)
def read_user_info(runtime: ToolRuntime[UserContext, Any]) -> UserInfo | str:
    """读取用户信息

    Returns:
        UserInfo | str: 如果找到用户信息,返回 UserInfo 对象;否则返回空字符串。
    """
    user_id = runtime.context.user_id            # ← 从 context 拿用户 id
    item = runtime.store.get(namespace, user_id)
    return UserInfo(**item.value) if item else ''

@tool(parse_docstring=True)
def write_user_info(user_info: UserInfo, runtime: ToolRuntime[UserContext, Any]) -> bool:
    """将用户信息写入长期记忆

    Args:
        user_info:用户信息对象

    Returns:
        bool: 如果成功写入则返回 True,否则返回 False
    """
    user_id = runtime.context.user_id
    runtime.store.put(namespace, user_id, user_info.model_dump())
    return True

agent = create_agent(
    model=model,
    tools=[read_user_info, write_user_info],
    store=store,
    checkpointer=InMemorySaver(),
    context_schema=UserContext,
)
跑起来是这样(课程输出):
写入记忆, namespace: ('users', 'user_info'), user_id: user_1, user_info: {'username': '韩立', 'age': 0, 'hobbies': ['修仙']}
写入记忆, namespace: ('users', 'user_info'), user_id: user_1, user_info: {'username': '韩立', 'age': 200, 'hobbies': ['修仙', '跑步']}
注意第二次写入的 hobbies 是 ['修仙', '跑步']——模型先 read_user_info 读回旧值,合并后再 write_user_info,所以旧爱好没丢。这就是 system prompt 里那句"在记录之前先查找历史信息,和新增信息合并后记录"的作用。
最后换 thread_2(全新的 thread_id)问"你还记得我吗?",模型照样能答上来——因为用户信息在共享的 store 里,不在某个 thread 的 messages 里。
课程在这段总结了五条:
| # | 结论 |
|---|---|
| 1 | 前两次 invoke 通过相同的 thread_id 串联为一个会话,共享短期记忆 |
| 2 | context 是运行时静态配置,每次 invoke 互相独立 |
| 3 | 长期记忆可以在任意位置访问,全局共享同一份信息 |
| 4 | 工具参数里的 ToolRuntime 是 LangChain / LangGraph 运行时注入的,在工具 schema 里没有体现 |
| 5 | ToolRuntime 的默认泛型是 [None, Any](第一个是 Context 的泛型,第二个是 State 的泛型) |
WARNING
ToolRuntime 不写泛型会踩坑。它的泛型默认值是 ContextT = TypeVar("ContextT", default=None)——不显式指定上下文类型,框架就认为"这个工具的 context 是 None"。这时 invoke(..., context=UserContext(...)) 会触发警告:
UserWarning | Pydantic serializer warnings:
  PydanticSerializationUnexpectedValue(Expected `none` - serialized value may not be as expected
    [field_name='context', input_value=UserContext(user_id='user_1'), input_type=UserContext])
所以课程把 UserContext 作为 ToolRuntime 的第一个泛型写出来:runtime: ToolRuntime[UserContext, Any]。
本机实测:写成 ToolRuntime[UserContext, Any] 后警告消失;写成裸 ToolRuntime 则复现上面这条 UserWarning(值其实照样注入进去了——runtime.context 拿得到 UserContext(user_id='user_1')——只是类型上不匹配,会报序列化警告)。
相关
练习题
一、知识回顾(读完直接做下面的实践题)
- 短期记忆记录的是会话级(线程)数据、会话间不共享;长期记忆记录的是用户特定或应用级数据,任何会话都能访问。LangChain 参考 CoALA 论文把长期记忆分成三类:**语义(Semantic)**记忆(事实)、**情景(Episodic)**记忆(经验,在 Agent 里常表现为 few-shot 示例)、**程序性(Procedural)记忆(规则/做事方法,比如系统提示词与工具调用规则)。写入长期记忆有两种时机:用户偏好、账号资料适合主流程(hot path)写,对话摘要、经验沉淀更适合后台(background)**写。
- 长期记忆是四层存储架构:Store(记忆仓库,常用实现是
InMemoryStore/PostgresStore)→ Namespace(层级路径,作用像文件夹,类型是tuple[str, ...])→ Key(该路径下的唯一标识,类型是str)→ Value(内容,类型是dict[str, Any])。 - 三个基础 API:
put()写入、get()读取、search()检索,它们可以在 Agent 执行流程之外直接调用。写入时的index参数有三档语义:默认None表示沿用 store 初始化时的索引配置;False表示不为这条数据建语义索引(存得下、搜不到);传字段路径列表表示只给指定字段建索引。ttl是可选**过期(存活)**时间,支不支持取决于具体 store 实现。 - 读取返回的不是裸字典而是
Item对象(字段有key/namespace/value/created_at/updated_at),所以取值要写item.value;get()的refresh_ttl控制"是否刷新当前条目的存活时间",默认None表示沿用创建 store 时的配置,没配置 TTL 时这个参数被忽略。两个时间戳在InMemoryStore里每次写入都被重置("更新"其实是新建),所以区分不出创建和修改;PostgresStore才是真正的更新——created_at固定、updated_at每次都变。 PostgresStore的用法和PostgresSaver完全对称:from_conn_string(DB_URL)上下文管理器 + 先跑一次store.setup()建表;把内存仓库换成它之后,工具代码一个字都不用改。在 psql 里\dt能看到六张表:PostgresSaver.setup()建的是 checkpoints、checkpoint_blobs、checkpoint_writes、checkpoint_migrations四张,PostgresStore.setup()再补上store和 store_migrations 两张;列出所有数据库用\l。PostgreSQL 的存储结构是 Database → Schema → Table 三层。- 检索用的
search():第一个位置参数是namespace_prefix(在该前缀下搜索);query走语义相似度检索(需要向量支持);filter用 value 里的键值对做结构化过滤(不需要向量,开箱即用);limit/offset相当于 SQL 的同名参数。返回的是SearchItem列表(额外携带匹配分数)。注意:只给query时返回的是"前缀下的全部条目",只是按分数降序排了序,默认limit=10只是把结果截到 10 条(截断)——所以语义检索一定要配合 limit 或 filter。 - 想让
search()支持语义检索,要在创建 store 时配置index:embed是"文本转向量"的嵌入函数(可以是自定义函数、嵌入模型对象,也可以直接写字符串模型名,如"openai:text-embedding-3-large");dims是输出向量维度,必须和 embed 实际产出的维度一致;fields决定给 value 里哪些属性建索引,四种路径写法——["$"]表示把整个 value 当作一个整体嵌入、["parent.child"]从嵌套对象里取子字段、["array[*].field"]从 JSON 数组的每个对象里逐个取。fields里每个元素都会生成一个向量,检索时底层做 max pooling(同一个 item 的多个向量取最高分)。 - 在工具里访问长期记忆:工具函数多接收一个
ToolRuntime参数(框架自动注入,不会出现在工具的 schema 里),通过runtime.store拿 store、runtime.state拿状态;创建 Agent 时要传store=参数把 store 交进去,自定义状态字段靠state_schema扩展。中间件里访问 store 有三条路径:Node-style 的四个钩子用runtime.store(runtime是第二个参数)、wrap_model_call和wrap_tool_call都用request.runtime.store。 - 两个 Runtime 别搞混:Node-style 钩子和
wrap_model_call拿到的是Runtime,字段是context/store/stream_writer/previous;wrap_tool_call的request.runtime是ToolRuntime,字段是state/context/config/stream_writer/tool_call_id/store(而ToolCallRequest自己的字段是tool_call/tool/state/runtime)。工具的泛型不能省:写成ToolRuntime[UserContext, Any]才不会在传 context 时报序列化 UserWarning;它默认的泛型是[None, Any](第一个是 Context、第二个是 State)。 - 静态运行时上下文(不可变的数据,比如用户元数据、数据库连接)三步走:用
@dataclass装饰器定义 ContextSchema → 创建 Agent 时用context_schema=声明 → 调用时用context=传入具体值。Node-style 钩子里用runtime.context访问,Wrap-style 钩子里用request.runtime.context。(课程 PDF 有一处把它误写成了state_schema,正确写法是context_schema;它和扩展状态用的state_schema是两个参数、可以一起用。)便捷中间件@dynamic_prompt用来自定义动态系统提示词——它只改"本次调用前的系统提示"、不写进消息列表,所以翻response["messages"]是看不到这条提示词的。最后记住三者分工:不变的东西放context、运行中变化的状态放state、跨会话共享的持久记忆放store。
二、裸写题
- 提示(先自己想,实在想不出再点开)
一级 · 思路:store 就是一个"带路径的字典",路径是元组、每层还能分组;索引配置是在创建仓库时给出的 二级 · 方法:
store.put(namespace, key, value)/store.get(...).value/store.search(前缀, filter={...});索引配置InMemoryStore(index={"embed": embed, "dims": 6, "fields": ["$", "course"]})三级 · 骨架:向量结构在store._vectors(私有属性,只为观察),形状是 namespace → key → 字段名 → 向量;时间戳看item.created_at/item.updated_at- 提示(先自己想,实在想不出再点开)
一级 · 思路:跨会话 = 记忆不在 thread 的 messages 里,而在所有会话共享的仓库里;工具拿仓库靠"框架注入的参数" 二级 · 方法:工具签名加
runtime: ToolRuntime;创建 Agent 时传store=store、state_schema=CustomState;自定义class CustomState(AgentState): user_id: NotRequired[str]三级 · 骨架:runtime.store.put(("users",), runtime.state["user_id"], {...});调用时带{"user_id": "user_1"};想让"同一个会话 / 新会话"这件事真的成立,给 Agent 配上checkpointer和会话 ID- 提示(先自己想,实在想不出再点开)
一级 · 思路:这是"读记忆 → 影响行为"的最短路径:身份从静态上下文来、偏好在长期记忆里 二级 · 方法:
@dynamic_prompt装饰的函数收request: ModelRequest,返回的字符串就是本次的 system prompt;request.runtime.context拿身份、request.runtime.store拿偏好;创建 Agent 时传context_schema=UserContext三级 · 骨架:return "# 用户偏好\n" + "\n".join(preferences);观察[type(m).__name__ for m in response["messages"]]——只有 Human / AI,没有 System- 提示(先自己想,实在想不出再点开)
一级 · 思路:
context是"启动时传入、运行中不变"的参数,天然适合放用户身份;工具里也能拿到它 二级 · 方法:@dataclass class UserCtx: user_id: str+create_agent(..., context_schema=UserCtx)+invoke(..., context=UserCtx(user_id="user_1"));工具里runtime.context.user_id,泛型写ToolRuntime[UserCtx, Any](不写会报序列化 UserWarning) 三级 · 骨架:用convert_to_openai_tool(你的工具)打印 schema——pydantic 参数会被展开成对象,ToolRuntime参数压根不出现
- 参考答案(做完再点开)
# ========== 本篇所有答案共用的开头(模型创建) ==========
import os

from dotenv import load_dotenv
from langchain.agents import create_agent
from langchain.chat_models import init_chat_model
from langchain_core.messages import HumanMessage

load_dotenv(override=True)

model = init_chat_model(
    model="deepseek-v4-flash",
    model_provider="openai",
    api_key=os.getenv("DEEPSEEK_API_KEY"),
    base_url=os.getenv("DEEPSEEK_BASE_URL"),
)

# ---------- 2-1 直接操作 store ----------
import time
from pprint import pprint

from langgraph.store.memory import InMemoryStore

store = InMemoryStore()
ns = ("users", "alice", "memories")
store.put(ns, "pref_food", {"category": "food", "text": "Alice likes sushi"})
store.put(ns, "pref_lang", {"category": "code", "text": "Alice prefers Python"})

item = store.get(ns, "pref_food")
print("① get:", item.value)                                  # 取回来的是 Item 对象,要 .value
print("② search 前缀:", [i.key for i in store.search(("users",))])
print("③ search + filter:", [i.key for i in store.search(ns, filter={"category": "code"})])

# ---- ④ 配一个自定义嵌入函数,看一条数据到底生成了几个向量 ----
def embed(texts: list[str]) -> list[list[float]]:
    return [[1.0] * 6 for _ in texts]

store_idx = InMemoryStore(index={"embed": embed, "dims": 6, "fields": ["$", "course"]})
store_idx.put(("users", "Alice", "memories"), "preferences",
              {"course": "计算机组成原理", "sports": "跑步"})
pprint(dict(store_idx._vectors))          # 私有属性,只为观察用
# 输出里能看到 'preferences' 下面挂了两个键:'$'(整个 value 的 JSON 字符串)+ 'course'(一级字段)
# → fields 里写几个路径,一条数据就生成几个向量;检索时底层做 max pooling

# ---- ⑤ 同一个 key 写两次,看时间戳怎么变 ----
before = store.get(ns, "pref_food")
time.sleep(1.2)
store.put(ns, "pref_food", {"category": "food", "text": "Alice 现在更喜欢火锅"})
after = store.get(ns, "pref_food")
print("改前 created_at:", before.created_at)
print("改后 created_at:", after.created_at)
print("created_at 变了吗:", before.created_at != after.created_at)
# True → InMemoryStore 的"更新"其实是新建:两个时间戳一起往后跳,区分不出创建和修改

# ---------- 2-2 让 Agent 自己记住用户信息(跨会话) ----------
from typing import NotRequired

from langchain.agents import AgentState
from langchain.tools import ToolRuntime, tool
from langgraph.checkpoint.memory import InMemorySaver

long_store = InMemoryStore()

class CustomState(AgentState):
    user_id: NotRequired[str]                 # 自定义状态字段:invoke 时一起传进来

@tool(parse_docstring=True)
def save_user_info(name: str, runtime: ToolRuntime) -> str:
    """将用户信息保存在长期记忆中

    Args:
        name: 用户名
    """
    runtime.store.put(("users",), runtime.state["user_id"], {"name": name})
    return f"已记住:{name}"

@tool(parse_docstring=True)
def get_user_info(runtime: ToolRuntime) -> str:
    """从长期记忆中读取用户信息"""
    item = runtime.store.get(("users",), runtime.state["user_id"])
    return str(item.value) if item else "unknown"

agent_mem = create_agent(
    model=model,
    tools=[save_user_info, get_user_info],
    store=long_store,                          # ← 不传的话工具里拿不到 store
    state_schema=CustomState,
    checkpointer=InMemorySaver(),
    system_prompt="用户提及个人信息时及时记录,用户询问个人信息时尝试用工具检索",
)

cfg1 = {"configurable": {"thread_id": "t1"}}
agent_mem.invoke({"messages": [HumanMessage("我叫韩立")], "user_id": "user_1"}, config=cfg1)
print("store 里现在有:", long_store.get(("users",), "user_1").value)

cfg2 = {"configurable": {"thread_id": "t2"}}    # ← 全新的会话(甚至换一次进程也一样,只要 store 是持久化的)
r = agent_mem.invoke({"messages": [HumanMessage("我叫什么?")], "user_id": "user_1"}, config=cfg2)
print("新会话回答:", r["messages"][-1].content)

# ---------- 2-3 按用户偏好动态生成系统提示 ----------
from dataclasses import dataclass

from langchain.agents.middleware import ModelRequest, dynamic_prompt

pref_store = InMemoryStore()
pref_ns = ("users", "preferences")
pref_store.put(pref_ns, "Ada Lovelace", {"chat_preferences": ["不喜欢啰嗦", "尽可能用最精简的文字解释清楚"]})
pref_store.put(pref_ns, "Blackwell", {"chat_preferences": ["喜欢长篇大论、引经据典"]})

@dataclass
class UserContext:
    username: str

@dynamic_prompt
def personalized_prompt(request: ModelRequest) -> str:
    username = request.runtime.context.username              # 静态上下文
    preferences = request.runtime.store.get(pref_ns, username).value["chat_preferences"]
    print(f"   [动态提示] {username} → {' / '.join(preferences)}")
    return "# 用户偏好\n" + "\n".join(preferences)            # ← 返回值就是本次的 system prompt

agent_pref = create_agent(
    model=model,
    middleware=[personalized_prompt],
    store=pref_store,
    context_schema=UserContext,
)

r_pref = agent_pref.invoke(
    {"messages": [HumanMessage("为什么花儿这样红?")]},
    context=UserContext(username="Ada Lovelace"),
)
print("state 里的消息:", [type(m).__name__ for m in r_pref["messages"]])
# 只有 HumanMessage / AIMessage —— 动态提示词压根不在消息列表里,所以每次调用都能重新算

# ---------- 2-4 静态运行时上下文:同一个 Agent 换身份 ----------
from typing import Any

from pydantic import BaseModel, Field

from langchain.agents.middleware import before_model
from langgraph.runtime import Runtime

@dataclass
class UserCtx:
    user_id: str

info_store = InMemoryStore()
info_ns = ("users", "user_info")

class UserInfo(BaseModel):
    """用户信息"""
    username: str = Field(description="用户名", default="unknown")
    age: int = Field(description="年龄", default=0)
    hobbies: list[str] = Field(description="兴趣爱好", default_factory=list)

@before_model
def show_context(state: AgentState, runtime: Runtime) -> dict[str, Any] | None:
    print(f"   [before_model] 本次的静态上下文: user_id={runtime.context.user_id}")
    return None

@tool(parse_docstring=True)
def read_user_info(runtime: ToolRuntime[UserCtx, Any]) -> str:
    """读取用户信息"""
    item = runtime.store.get(info_ns, runtime.context.user_id)     # ← 用户 id 来自 context
    return str(item.value) if item else "没有任何记录"

@tool(parse_docstring=True)
def write_user_info(user_info: UserInfo, runtime: ToolRuntime[UserCtx, Any]) -> str:
    """将用户信息写入长期记忆

    Args:
        user_info: 用户信息对象
    """
    runtime.store.put(info_ns, runtime.context.user_id, user_info.model_dump())
    return "写入成功"

agent_ctx = create_agent(
    model=model,
    tools=[read_user_info, write_user_info],
    store=info_store,
    middleware=[show_context],
    context_schema=UserCtx,            # ← 声明用哪个 schema(不是 state_schema)
)

# 同一个 Agent,两次调用传不同的 context → 落到不同的长期记忆槽位
agent_ctx.invoke({"messages": [HumanMessage("记一下:我叫韩立,今年 200 岁,爱好修仙")]},
                 context=UserCtx(user_id="user_1"))
print("user_1 的记忆:", info_store.get(info_ns, "user_1").value)

r_other = agent_ctx.invoke({"messages": [HumanMessage("我之前告诉过你什么?")]},
                           context=UserCtx(user_id="user_2"))
print("user_2 的记忆:", info_store.get(info_ns, "user_2"))
print("user_2 的回答:", r_other["messages"][-1].content[:40])     # 查不到 → 两个身份互不串门

# 顺带核对:工具参数用 pydantic 模型时,schema 里参数被展开、注入的运行时参数不出现
from langchain_core.utils.function_calling import convert_to_openai_tool

print("write_user_info 的 schema:", convert_to_openai_tool(write_user_info)["function"]["parameters"]["properties"].keys())
三、综合题
- 模型调用前:按本次调用传进来的用户身份,从长期记忆里读出该用户能用哪些工具,把不能用的从这次请求的工具集里去掉(只对本次生效,不能污染下一轮),并为每个被去掉的工具打印一行日志;
- 工具调用前:算出本次工具调用要花多少额度(自己定一张价目表);够就扣掉并写回长期记忆(同一个用户的其他字段要保住),然后放行真工具;不够就不执行真工具、直接返回一条"额度不足"的工具结果——注意把工具调用的编号回填进去,否则模型那边等不到回音;
- Agent 跑完之后:从长期记忆里读出最新额度打印出来。
用三个用户各跑一次(一个额度充足、一个没有天气工具权限、一个额度太少),把日志和仓库里的剩余额度对照着看,并解释:为什么被拦下的那次额度一分没扣?
- 提示(先自己想,实在想不出再点开)
一级 · 思路:两道闸门都在 wrap-style(包裹)钩子里:一个改"发往模型的请求",一个管"工具到底执行不执行";身份和额度都从运行时对象上取 二级 · 方法:类写法的
wrap_model_call(request, handler)用request.override(tools=...)改本次工具集,再return handler(request);wrap_tool_call(request, handler)拒绝时返回Command(update={"messages": [ToolMessage(content=..., tool_call_id=request.runtime.tool_call_id)]}),放行时return handler(request)三级 · 骨架:两个钩子都用request.runtime.context取身份、request.runtime.store取仓库;额度不足就别调 handler;after_agent(state, runtime)里打印最新额度;@wrap_model_call也可以写成类里的方法
- 参考答案(做完再点开)
# ========== 综合题答案(模型创建部分同上) ==========
import os
from dataclasses import dataclass
from typing import Any, Callable

from dotenv import load_dotenv
from langchain.agents import create_agent
from langchain.agents.middleware import AgentMiddleware, ModelRequest, ModelResponse, ToolCallRequest
from langchain.chat_models import init_chat_model
from langchain.tools import tool
from langchain_core.messages import HumanMessage, ToolMessage
from langgraph.store.memory import InMemoryStore
from langgraph.types import Command

load_dotenv(override=True)

model = init_chat_model(
    model="deepseek-v4-flash",
    model_provider="openai",
    api_key=os.getenv("DEEPSEEK_API_KEY"),
    base_url=os.getenv("DEEPSEEK_BASE_URL"),
)

@dataclass
class UserContext:          # 2-3 里定义过,这里重复给出,方便本段独立运行
    username: str

# ---------- 3-1 综合:额度校验 + 按身份裁剪工具集 + 计费写回 ----------

credit_store = InMemoryStore()
credit_ns = ("users", "credits")
credit_store.put(credit_ns, "Ada Lovelace", {"tokens_left": 3000, "get_weather": "yes", "get_news": "no"})
credit_store.put(credit_ns, "Blackwell", {"tokens_left": 2000, "get_weather": "no", "get_news": "yes"})
credit_store.put(credit_ns, "Ampere", {"tokens_left": 5, "get_weather": "yes", "get_news": "yes"})

CREDIT_MAP = {"get_weather": 10, "get_news": 20}      # 每个工具的"话费"

@tool
def get_weather(city: str) -> str:
    """查询指定城市当日天气

    Args:
        city: 城市名称
    """
    return f"{city} 今天天气不错"

@tool
def get_news() -> str:
    """查询当日新闻"""
    return "今日新闻:美伊尚未达成停战协议"

class CreditGuard(AgentMiddleware):
    """① 按身份裁剪工具集 ② 按额度放行/拦截工具 ③ 扣费写回长期记忆"""

    def wrap_model_call(self, request: ModelRequest, handler: Callable[[ModelRequest], ModelResponse]):
        context = request.runtime.context           # 静态上下文
        store = request.runtime.store               # 长期记忆
        value = store.get(credit_ns, context.username).value

        allowed = [t for t in request.tools if value.get(t.name) == "yes"]
        for t in request.tools:
            if value.get(t.name) != "yes":
                print(f"   [wrap_model_call] {context.username} 无权调用 {t.name}")
        # 只改本次请求携带的工具集(transient),下一轮 request.tools 又是全量
        return handler(request.override(tools=allowed))

    def wrap_tool_call(self, request: ToolCallRequest, handler: Callable[[ToolCallRequest], ToolMessage | Command[Any]]):
        store = request.runtime.store
        context = request.runtime.context
        value = store.get(credit_ns, context.username).value

        cost = CREDIT_MAP.get(request.tool.name, 0)
        if value["tokens_left"] < cost:
            print(f"   [wrap_tool_call] {context.username} 额度不足,{request.tool.name} 调用失败")
            # 不调 handler → 工具根本没执行;但必须回填 tool_call_id,否则模型那边等不到回音
            return Command(update={"messages": [ToolMessage(
                content="额度不足,无法调用工具,请充值~",
                tool_call_id=request.runtime.tool_call_id,
            )]})

        value["tokens_left"] -= cost
        store.put(credit_ns, context.username, value)      # 整份 value 写回,其他字段一起保留
        print(f"   [wrap_tool_call] {context.username} 调用 {request.tool.name} 花费 {cost},剩余 {value['tokens_left']}")
        return handler(request)

    def after_agent(self, state, runtime):
        username = runtime.context.username
        item = runtime.store.get(credit_ns, username)
        print(f"   [after_agent] {username} 当前剩余额度:{item.value['tokens_left']}")
        return None

agent_guard = create_agent(
    model=model,
    middleware=[CreditGuard()],
    tools=[get_weather, get_news],
    store=credit_store,
    context_schema=UserContext,
)

for name in ["Ada Lovelace", "Blackwell", "Ampere"]:
    print(f"===== {name} =====")
    rr = agent_guard.invoke({"messages": [HumanMessage("帮我查一下北京今天的天气")]},
                            context=UserContext(username=name))
    print("   最终回答:", str(rr["messages"][-1].content)[:60])
    print("   store:", credit_store.get(credit_ns, name).value)